Here's the tension: some researchers aim to shrink AI's compute cost, while others study its impact on mathematics, reasoning, and social habits. This list runs from local model serving to agent societies. Each paper earned its spot with a concrete technical shift, a useful question, or a result demanding careful replication.
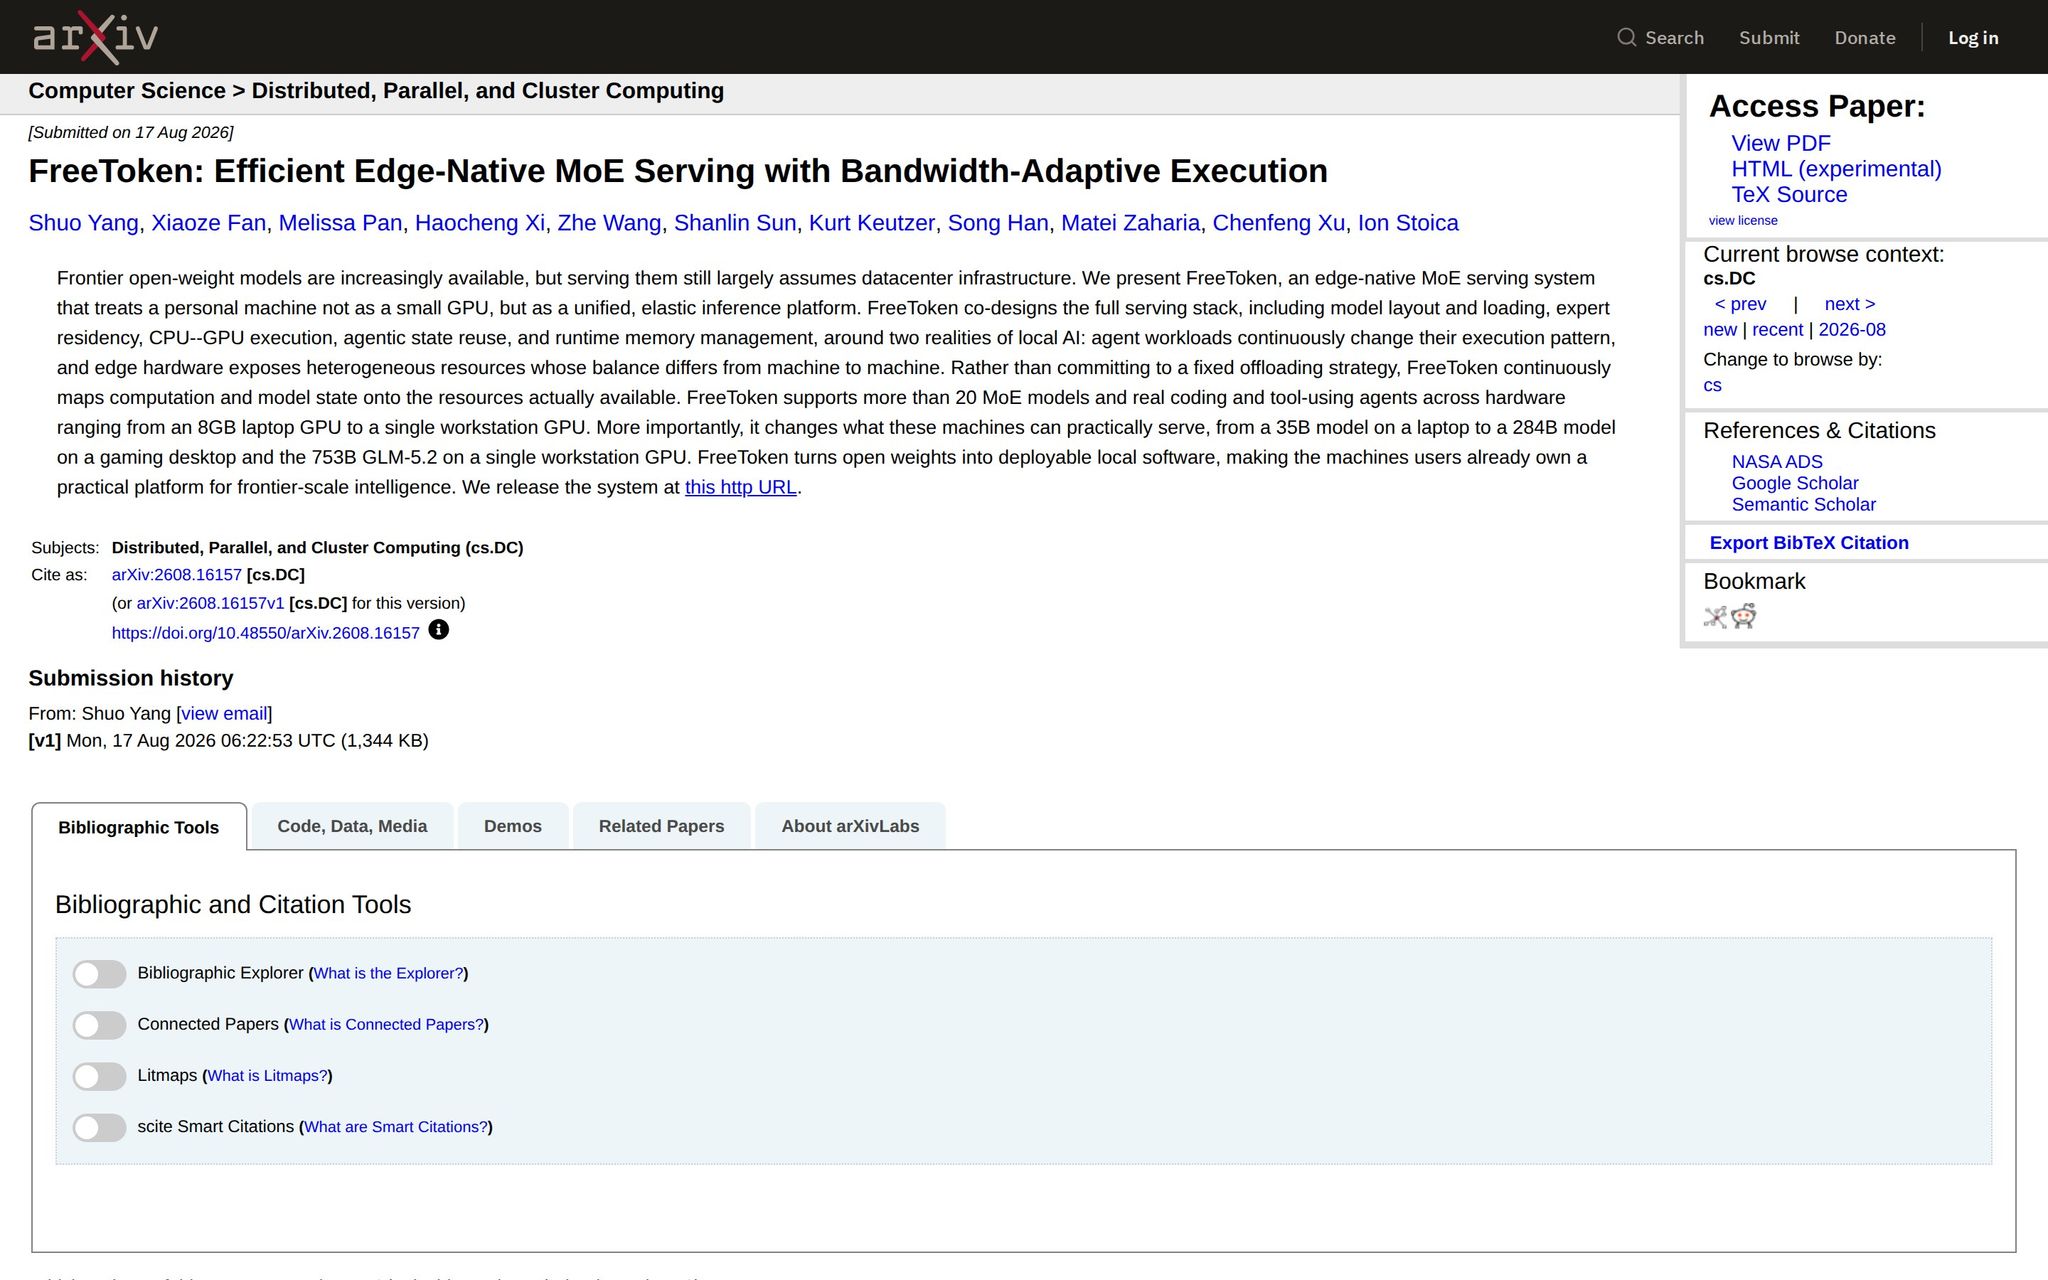
1. FreeToken: Efficient Edge-Native MoE Serving with Bandwidth-Adaptive Execution
What It Does
Runs mixture-of-experts models on personal computers by adapting to data-transfer speed, enabling local serving without a remote data center.
Why It's Trending
Landed in August 2026 as open-source coverage highlighted local MoE serving on modest hardware.
The Big Idea
Treat your laptop as a flexible inference platform. The system measures bandwidth and changes its work pattern accordingly.
Key Findings
- Targets consumer and workstation hardware.
- Execution adapts to measured bandwidth limits.
- Real-world evaluation on personal hardware.
- Related discussion mentions speedups from 2.4x to 16.1x (unverified).
- GitHub repository is available.
What Makes It Different
Bandwidth-aware execution built for edge hardware, assuming consumer-grade connections, not data-center resources.
Why It Matters
- Could improve local model inference.
- Reduces dependence on centralized hardware.
- Helps privacy-sensitive assistants.
- Part of the push toward smaller, accessible AI.
Potential Applications
- Running a local coding assistant.
- Serving a private document assistant.
- Deploying an offline field-service model.
- Testing MoE systems on consumer hardware.
What the Researchers Found
The paper describes evaluation on consumer hardware. Feasibility is the stronger finding; the speed claim is unverified.
Things to Consider
- Verification: the snippet doesn't confirm the headline speed figure.
- Reproducibility: code at FlashML-org/FreeToken.
- Hardware fit: tied to consumer evaluations.
- Real-world test: bandwidth and model size dictate practicality.
Our Verdict
Useful for developers needing local MoE serving, provided they test the repository on their hardware first.
arXiv: https://arxiv.org/abs/2608.16157
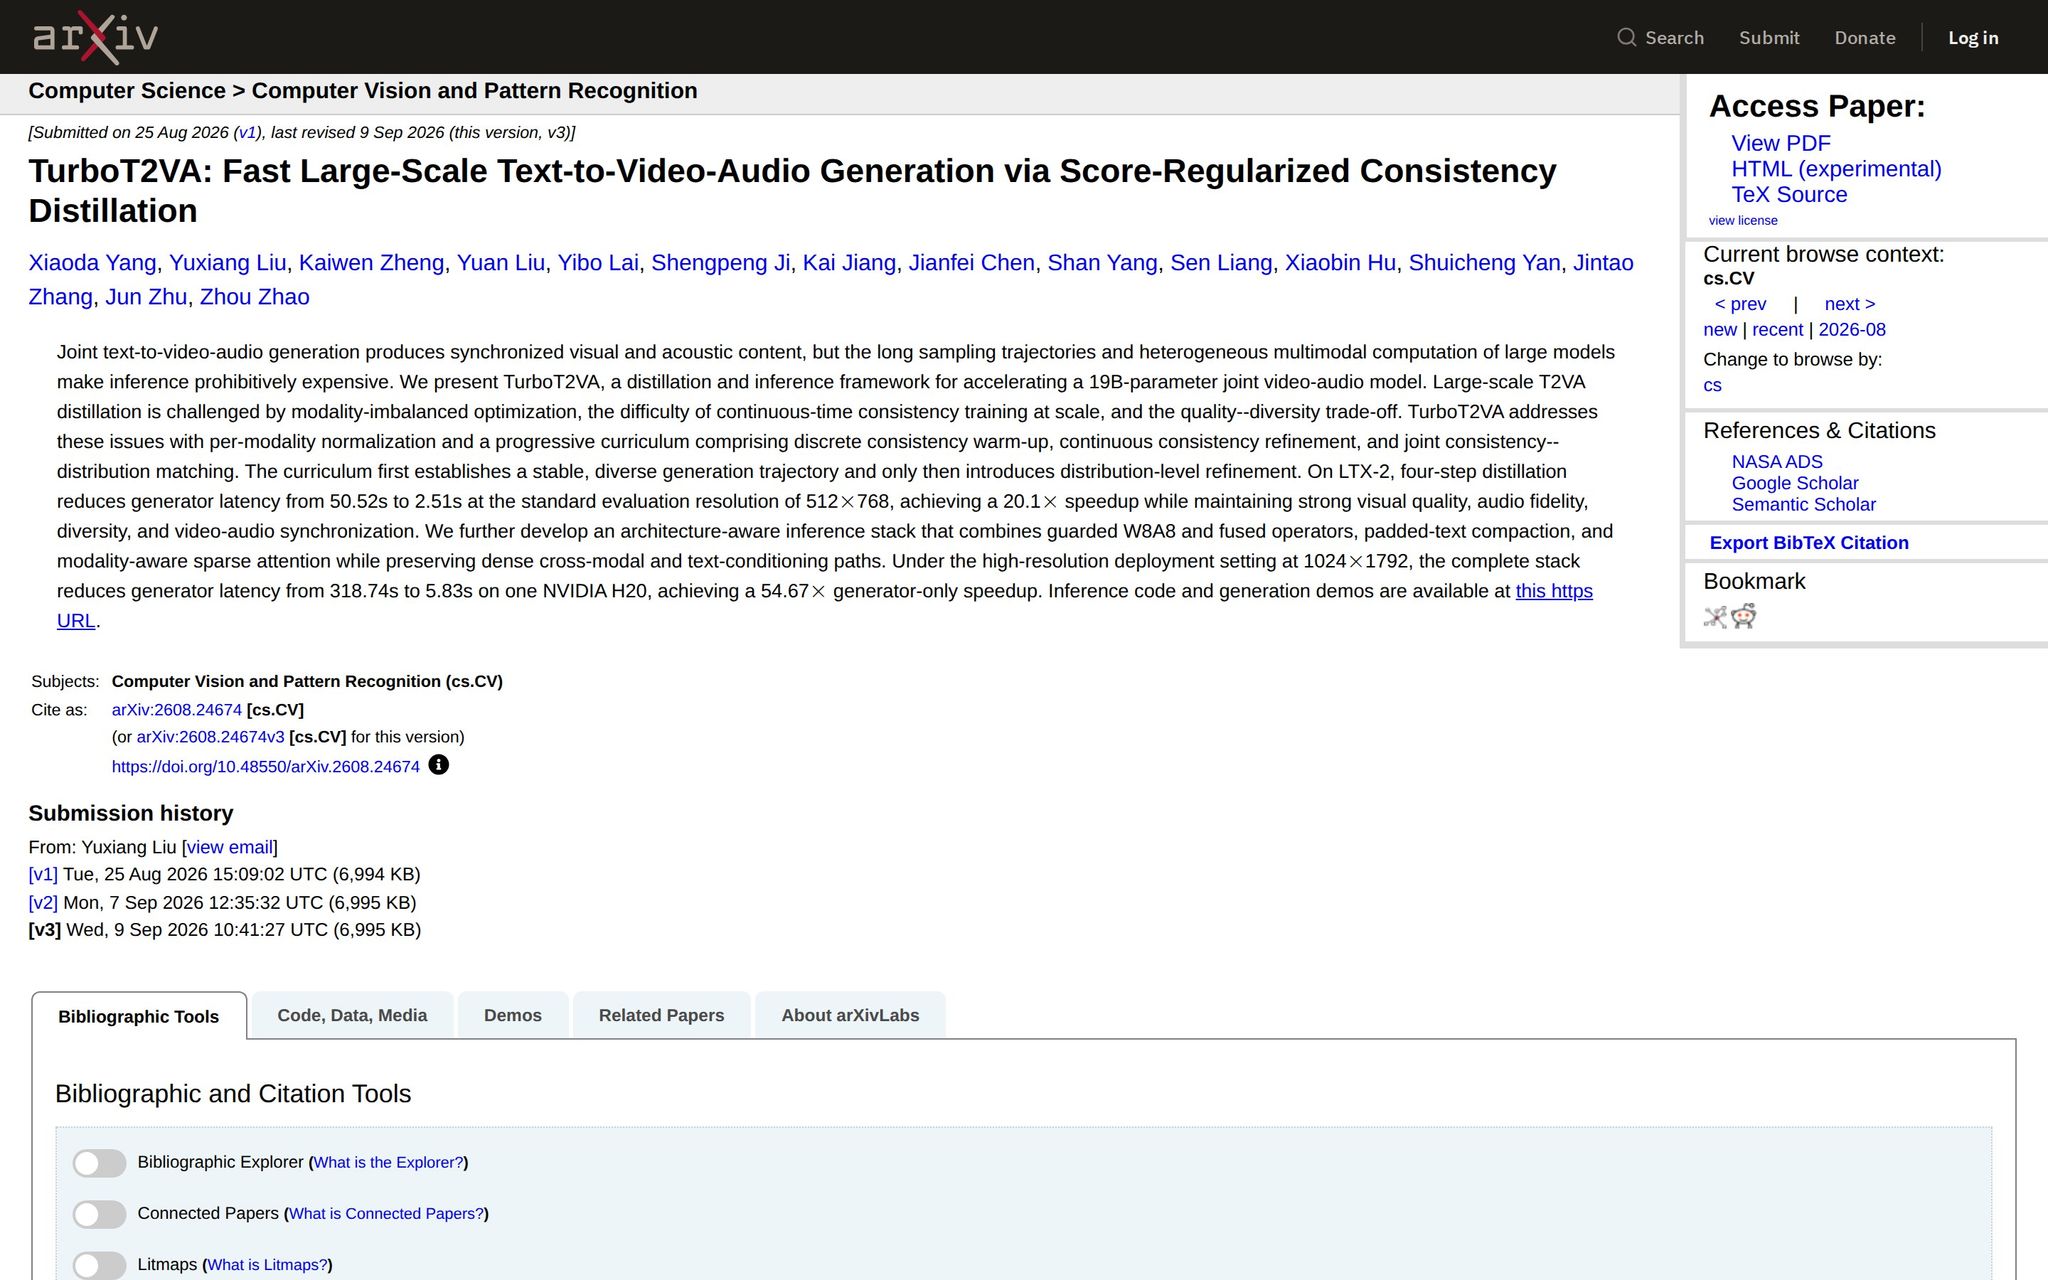
2. TurboT2VA: Fast Large-Scale Text-to-Video-Audio Generation via Score-Regularized Consistency Distillation
What It Does
Generates video and audio from text faster by training a fast generator to imitate a slower one while preserving quality.
Why It's Trending
Drew chatter in August 2026 for reporting a 20.1x cut in generator latency.
The Big Idea
Skip repeated small steps. Train the system to take a shortcut that slashes generation time.
Key Findings
- Reported generator-latency speedup is 20.1x.
- Targets large-scale text-to-video-audio generation.
- Method uses score-regularized consistency distillation.
- Evaluated model has 19 billion parameters.
What Makes It Different
Applies consistency distillation to a combined video-and-audio generator, not a single-media system.
Why It Matters
- Could make multimodal generation more responsive.
- Addresses the cost of repeated steps.
- Benefits interactive media tools.
- Reflects pressure to cut latency.
Potential Applications
- Creating rapid storyboards with sound.
- Generating draft training videos.
- Previewing game scenes.
- Producing accessible video variants.
What the Researchers Found
Reports a 20.1x generator-latency speedup while maintaining benchmark quality. The baseline hardware is unspecified.
Things to Consider
- Benchmark context: missing baseline conditions.
- Reproducibility: authors and code release aren't exposed.
- Scale: uses a 19B-parameter model.
- Production reality: quality and latency may differ.
Our Verdict
Potentially valuable for interactive video tools. Its 20.1x claim matters only after independent reproduction.
arXiv: https://arxiv.org/abs/2608.24674
3. Improving matrix multiplication exponent with AlphaEvolve optimization
What It Does
Searches for better ways to multiply matrices using AlphaEvolve optimization, reporting a new theoretical upper bound.
Why It's Trending
The August 2026 result attracted discussion because matrix multiplication underpins model training.
The Big Idea
Let a system search possible recipes for multiplying grids. A better recipe changes the theoretical limit.
Key Findings
- Claims an upper bound of omega < 2.371177.
- Result is theoretical.
- Search uses AlphaEvolve-style optimization.
- No measured hardware speedup provided.
What Makes It Different
Uses automated search to discover mathematical constructions, not hand-designing an improvement.
Why It Matters
- Could inform future matrix libraries.
- Addresses the cost of a core AI operation.
- May improve scientific computing.
- Represents machine-assisted algorithm design.
Potential Applications
- Designing future neural-network kernels.
- Improving large scientific simulations.
- Exploring hardware accelerator strategies.
- Teaching automated systems mathematical search.
What the Researchers Found
Claims a new upper bound, omega < 2.371177. No baseline runtime is given.
Things to Consider
- Practicality: no hardware benchmark supplied.
- Reproducibility: authors and code aren't exposed.
- Interpretation: a better exponent doesn't guarantee faster real workloads.
- Status: a mathematical claim needing scrutiny.
Our Verdict
Significant for algorithm theorists. Application teams should wait for concrete implementations.
arXiv: https://arxiv.org/abs/2608.16884
4. Autonomous Mathematical Discovery in an Open-World Multi-Agent Environment
What It Does
Places AI agents in a shared workspace to pursue mathematical questions together, producing constructions and analyses.
Why It's Trending
Published August 2026 for claiming novel results, not just solving prewritten tasks.
The Big Idea
Agents build on one another in a research room with shared notes and common goals.
Key Findings
- Agents collaborated in the Station environment.
- Targeted open-world mathematical discovery.
- Produced numerical constructions and theoretical analyses.
- Evaluation wasn't a standard benchmark.
What Makes It Different
Its open-ended research setting evaluates collaborative discovery, not accuracy on a fixed set.
Why It Matters
- Could improve AI-assisted hypothesis generation.
- Addresses narrow benchmark tasks.
- May support scientific exploration.
- Represents a shift toward goal-pursuing agents.
Potential Applications
- Searching for candidate proofs.
- Exploring numerical patterns.
- Generating hypotheses for mathematicians.
- Organizing competing solution attempts.
What the Researchers Found
Reports novel mathematical results. No count, baseline, or independent confirmation is supplied.
Things to Consider
- Benchmark limitation: not a standard evaluation.
- Verification: novelty needs expert checking.
- Reproducibility: authors and code aren't exposed.
- Real-world transfer: may not yield reliable work.
Our Verdict
A promising experiment for discovery-oriented agents, conditional on human verification.
arXiv: https://arxiv.org/abs/2608.23691
5. DeepVoyager-VL: Incentivizing Vision-in-the-Loop Search for Long-Horizon Multimodal Agents
What It Does
Helps a multimodal agent search using visual evidence over multiple steps, where images guide what to retrieve next.
Why It's Trending
Appeared August 2026, claiming to surpass proprietary models.
The Big Idea
Vision acts as a clue throughout. Each image can trigger another search.
Key Findings
- Keeps vision active during search.
- Targets long-horizon multimodal tasks.
- Visual evidence triggers continued retrieval.
- Claims results above proprietary models.
What Makes It Different
Makes visual evidence part of the control loop, not just a start or end input.
Why It Matters
- Could improve multi-step visual research.
- Addresses brittle one-shot image understanding.
- May benefit assistants using charts and screens.
- Represents more deliberate agent behavior.
Potential Applications
- Searching product catalogs from photos.
- Investigating technical diagrams.
- Navigating visual web research.
- Checking images during field inspection.
What the Researchers Found
Claims strong benchmark performance and surpassing proprietary models. No score or baseline details are supplied.
Things to Consider
- Benchmark context: missing headline number.
- Reproducibility: released assets aren't identified.
- Real-world cost: long searches increase expense.
- Evaluation: comparisons need matched conditions.
Our Verdict
Relevant for visual research agents, provided developers inspect missing details and measure cost and reliability.
arXiv: https://arxiv.org/abs/2608.01827
6. Large-Language Models as a Cognitive Virus
What It Does
Uses a viral analogy to study how LLM adoption spreads through populations, examining diffusion, tipping points, and dependence.
Why It's Trending
Published September 2026 as AI adoption accelerated.
The Big Idea
Treat adoption like a contagion: exposure leads to more exposure, potentially changing group behavior.
Key Findings
- Models LLM spread through populations.
- Focuses on cognitive practices.
- Proposes possible tipping points.
- Discusses dependence and lock-in.
What Makes It Different
Connects LLM deployment with complex systems and biology. A conceptual lens, not a new model.
Why It Matters
- Could improve adoption risk assessment.
- Addresses dependence benchmarks miss.
- May inform education and policy.
- Represents broader societal study.
Potential Applications
- Planning workplace rollouts.
- Studying AI dependence in education.
- Modeling adoption for public services.
- Designing safeguards against lock-in.
What the Researchers Found
Argues contagion-like diffusion can create tipping points. No empirical validation is supplied.
Things to Consider
- Evidence: conceptual, not empirical.
- Interpretation: 'virus' is a metaphor.
- Reproducibility: no code release.
- Real-world patterns: adoption varies.
Our Verdict
Useful framing for policy teams, but only as a hypothesis-generating lens. Decisions need measured data.
arXiv: https://arxiv.org/abs/2609.03344
7. SwarmWorld: Collective intelligence among language-model agents
What It Does
Studies groups of LM agents coordinating in a simulation to form self-organizing societies.
Why It's Trending
The August 2026 paper applied collective-intelligence language to agent systems.
The Big Idea
Agents coordinate without a central manager. Local interactions produce group behavior.
Key Findings
- Studies multiple LM agents.
- Examines self-organizing societies.
- Setting is a simulation.
- Focus is collective behavior.
What Makes It Different
Treats coordination and organization as the study object, not just a tool.
Why It Matters
- Could improve agent coordination.
- Addresses group-scale behavior.
- May inform agent governance simulations.
- Represents a move toward societies.
Potential Applications
- Coordinating research assistants.
- Simulating negotiation among agents.
- Testing multi-agent marketplace rules.
- Studying failure spread in teams.
What the Researchers Found
Explores self-organization descriptively. No numerical result or benchmark is reported.
Things to Consider
- Benchmark limitation: no values exposed.
- Validation: observed coordination must repeat.
- Reproducibility: authors and code not identified.
- Real-world transfer: simulated may not predict deployed.
Our Verdict
A conceptual study for multi-agent designers. Treat behaviors as exploratory; demand quantitative tests.
arXiv: https://arxiv.org/abs/2608.26081
8. Emergent Symbolic Structure in artificial neural networks
What It Does
Analyses whether neural networks develop internal patterns resembling symbols and rules.
Why It's Trending
Published August 2026, joining discussion about organized internal representations.
The Big Idea
Look inside for reusable labels and relationships, checking for rule systems beyond memorization.
Key Findings
- Investigates symbolic structure inside networks.
- Analyzes internal representations.
- Targets symbolic reasoning capability.
- It's a research analysis.
What Makes It Different
Studies internal organization supporting symbolic behavior, not proposing a new model.
Why It Matters
- Could improve model reasoning explanations.
- Addresses the gap between output and structure.
- May help diagnose reasoning failures.
- Represents deeper representation study.
Potential Applications
- Inspecting reasoning in educational models.
- Auditing structured classifier decisions.
- Designing models for rule-heavy tasks.
- Comparing internal patterns.
What the Researchers Found
Investigates symbolic structure emergence. No benchmark value is supplied.
Things to Consider
- Evidence: no quantitative values exposed.
- Reproducibility: authors and code not identified.
- Interpretation: symbolic-looking patterns may not prove reasoning.
- Status: analytical, not deployed.
Our Verdict
For interpretability researchers. Value depends on whether signals predict behavior.
arXiv: https://arxiv.org/abs/2608.29530
9. Mathematics in the age of AI
What It Does
Examines how AI may change mathematical research, from finding ideas to shaping practice.
Why It's Trending
Appeared August 2026 as AI-assisted math became a practical question.
The Big Idea
AI may collaborate, suggest paths, check work, or change which problems mathematicians attempt.
Key Findings
- Surveys AI's role in math research.
- Discusses implications for practice.
- It's a perspective, not a benchmark.
What Makes It Different
Synthesizes the research ecosystem and human practice, not optimizing a single task.
Why It Matters
- Could improve planning for AI-assisted research.
- Addresses changes model scores miss.
- May help set expectations.
- Represents societal analysis.
Potential Applications
- Designing human-AI math workflows.
- Planning training for researchers.
- Setting review standards.
- Choosing tasks to automate.
What the Researchers Found
Discusses AI's implications. No measured capability gain is provided.
Things to Consider
- Evidence: a perspective, not a performance study.
- Reproducibility: authors and code not exposed.
- Scope: claims may vary across disciplines.
- Real-world change: depends on human review.
Our Verdict
Useful orientation for math departments and AI developers. Distinguish strategic perspective from evidence.
arXiv: https://arxiv.org/abs/2608.16753
10. Beacon: Knowing When and How to Perform Agentic Visual Reasoning
What It Does
Helps a multimodal model decide when visual reasoning needs extra steps and how to proceed.
Why It's Trending
Updated in August 2026, addressing controlling reasoning cost in visual agents.
The Big Idea
Beacon navigates, choosing when to stop, inspect, or reroute. It controls visual work based on task need.
Key Findings
- Framework for agentic visual reasoning.
- Decides when to invoke reasoning steps.
- Decides how to proceed visually.
- Evaluation is benchmark-based.
What Makes It Different
Focuses on control: deciding when and how to reason, not just adding processing.
Why It Matters
- Could reduce wasted visual reasoning.
- Addresses fixed-depth processing cost.
- May benefit document and image agents.
- Represents more selective behavior.
Potential Applications
- Answering questions about long documents.
- Navigating software interfaces.
- Inspecting images only when needed.
- Building lower-cost assistants.
What the Researchers Found
Reports a framework and benchmark evaluation. No score or detailed comparison is exposed.
Things to Consider
- Benchmark context: headline numbers not visible.
- Reproducibility: code release not verifiable.
- Cost: measure control overhead.
- Status: benchmarked, not a deployed service.
Our Verdict
Sensible for managing multimodal budgets. Confirm benchmark details show policy saves work without hiding errors.
arXiv: https://arxiv.org/abs/2607.28595
Together, these papers point in two directions: cheaper computation and deeper questions about collective behavior. Try FreeToken's code first. Inspect benchmark conditions before trusting speed claims.
Treat the society and mathematics papers as frameworks for questions, not settled evidence.