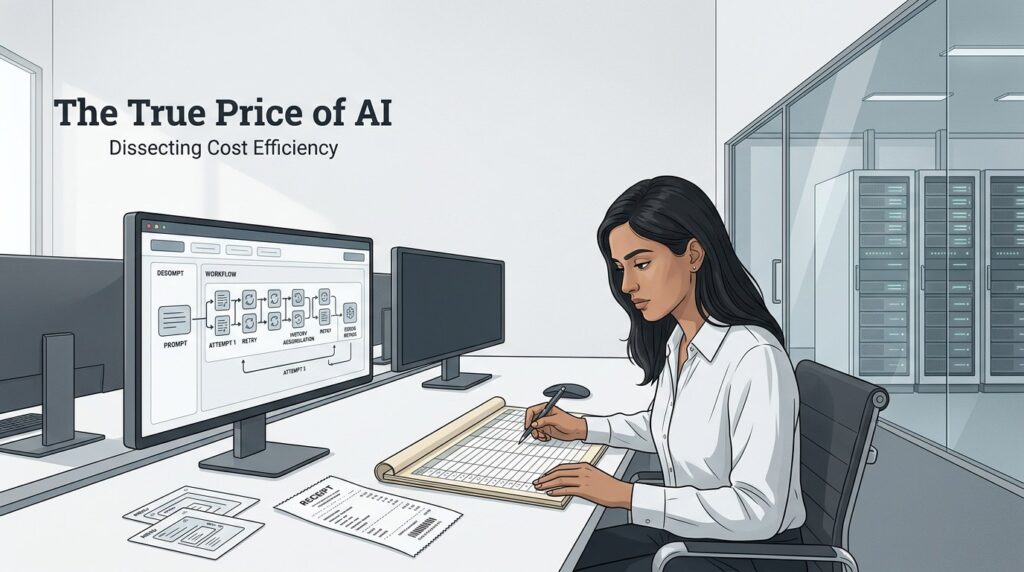
Priya’s model was cheap. Her workflow was not.
Since 2020, the advertised price of generating text has plunged, and 2026’s price pages can make serious AI work look like a rounding error. Yet a low rate does not explain why a power user can still produce a bill in the hundreds, or why a task that finishes quickly can leave an expert with hours of repairs.
The missing money sits between the prompt and the finished job: repeated steps, oversized menus, accumulated history, failed attempts and human checking. Follow Priya from a seductive price page to an itemized receipt, and the apparent contradiction becomes a practical rule. The cheapest model can run the more expensive system; a well-designed system can make the same model materially cheaper.
The Scene
At 11:07 on a Monday, Priya, a senior engineer, has two browser tabs open and a budget meeting in 23 minutes. One tab advertises model access at $0.15 per million input tokens. The other shows the internal estimate for the company’s busiest users: hundreds of dollars each month.
She leans toward the invoice and finds no single runaway request. Instead, every support task has left crumbs: instructions loaded again, a long list of available actions, database results copied into the conversation, another attempt after the first went wrong, and a human checking whether the polished answer actually fixed anything.
Priya has been asked to choose between a cheaper model and an engineering sprint to rebuild the workflow around the current one. The cheaper-model slide is easy to defend. The rebuild means telling finance that the number printed largest on the price page is not the number that governs the bill.
She circles “model rate,” then writes beside it: “Price of what?” Buy cheaper words, or make the system read less.
The Question Everyone Asks
Does a cheaper AI model actually make the work cheaper?
For Priya, the honest answer determines whether her team changes supplier or changes its own design. For everyone else, it determines whether an AI savings claim describes a finished job or merely one ingredient inside it.
The question is difficult because the units do not match. Price pages charge for text processed, while companies care about resolved tickets, reviewed code and completed designs. A system can consume inexpensive text repeatedly, call outside services, retry failures and still require an employee to inspect the result.
That makes two familiar answers unreliable. “Tokens are cheap” ignores everything wrapped around them; “AI is expensive” ignores systems that genuinely reduce waste. Heena J. V. Shah, Senior Solutions Engineer AI at Microsoft, offered the better starting point in September 2026: “The place to start is the receipt.
What does the model actually read on one turn, and who put it there?”
The Pitch
The deck in front of Priya begins with the cleanest number available. As of August 2026, GPT-4o-mini was listed at $0.15 per 1 million input tokens and $0.60 per 1 million output tokens. That sounds almost free because it prices the words, not the work.
Tokens are the small chunks of text counted on the bill, much as a phone plan counts data rather than conversations. A June 2026 pricing guide estimated that 1,000 English words equal about 1,333 tokens.
Then the demo upgrades from chat to an agent. An agent is a program that chooses its next step so it can carry a task through several stages instead of answering once.
To act, it receives tools, meaning outside actions such as searching a database, opening a ticket or running a command. Think of the tool menu as the list of departments a shop assistant can contact: the longer the directory, the more the system may have to read before deciding where to go.
Finally comes context, the prompts, history and tool results the model can read during one call. A larger context is like a larger desk: useful when the right papers are spread across it, wasteful when every old receipt remains in the pile.
Maya Chen, VP of Agent Operations at Talendium AI, which builds and runs HR agents, put the omitted line plainly: “The model line is rarely the whole receipt; every handoff, retry and review has to earn its place.”
“The model line is rarely the whole receipt; every handoff, retry and review has to earn its place.”
— Maya Chen, VP of Agent Operations, Talendium AI
What the Evidence Shows
The headline answer is no: a cheaper model does not necessarily make an agent workflow cheaper. Recent evidence suggests the design around the model can consume more of the bill than the customer’s actual request.
In September 2026, Shah tested five designs for a telecom-support agent using the same model and 18 tools. Her proof-of-concept included 25 single-turn questions and five scripted conversations. In the baseline, 73% of what the model read each turn was the tool menu, accounting for roughly 63% of per-turn cost before the customer’s question arrived.
She then changed who saw which tools, not the underlying model. Sending billing questions only to billing tools produced about half the cost with latency essentially flat. In a three-step draft, review and refinement pattern, directing each step to a smaller menu cut cost by a quarter.
“If your POC can’t itemize a turn, you aren’t doing tokenomics — you’re doing token guessing,” Shah wrote. That warning matters: tool-menu sizes were modeled, and correctness was not yet scored, so her dollar estimates are directional rather than production invoices.
A second early test found the same waste in tool results. Context Mode, an open-source coding project, reported in May 2026 that it reduced a 56.2 KB browser snapshot to 299 bytes and a full session’s 315 KB of raw output to 5.4 KB.
Its maintainers said the change extended sessions from about 30 minutes to about three hours before old material had to be compressed. Those project benchmarks were published with scenario scripts but have not been independently replicated.
In Shah’s baseline test, the menu of available tools occupied 73% of what the model read on each turn—before it could address the customer’s question.
“If your POC can’t itemize a turn, you aren’t doing tokenomics — you’re doing token guessing.”
— Heena J. V. Shah, Senior Solutions Engineer AI at Microsoft
The Other Side
The strongest case against Priya’s concern is that raw model access really has become dramatically cheaper. A May 2026 analysis, citing provider data, reported that generating 1 million tokens fell from about $60 in 2020 to roughly $0.05 in 2025, a 1,200× decline. That is a genuine efficiency gain, not accounting theater.
Capability can also arrive quickly. In September 2026, a game developer reported using GPT-6 Astra with Blender to construct a roughly 35-meter hospital corridor, furnished rooms and a cinematic flythrough in about 45 minutes. For concept work, that speed could be valuable even without perfect cost logs.
But the demonstration reported no token or computing bill. Another 3D practitioner testing the same approach found “only an 80% solution” and said the mesh would require a complete overhaul despite a decent silhouette.
The two accounts can both be true. Cheap generation lowers the entry price; tool calls, retries and expert rework determine whether the finished result is economical. Speed is evidence of usefulness, not by itself evidence of savings.
Rapid generation can lower the cost of a first draft; the economics depend on what must be rebuilt before anyone accepts it.
What It Means for You
Verdict — opinion: AI models are genuinely cheaper, but a cost-efficiency claim deserves belief only when it prices a completed, checked task. Shah’s early test suggests that limiting what each step reads can cut token cost by about 25% to 50% without changing the model.
Because correctness was not scored and the result has not been independently replicated, that range is a design clue, not a universal promise.
First, at work this week, choose one repeated task and demand a receipt for a single run: input and output tokens, tools shown, tools used, number of steps, retries, outside-service charges and human review minutes.
Second, run a two-way test. Keep the model fixed, then give each request only the instructions and tools it needs. Compare total cost and accepted results, not merely model rates.
Talendium AI’s Chen is right that each handoff must earn its place.
Third, in the next AI-budget conversation, ask one sentence: “Cheaper per million tokens, or cheaper per approved job?” If nobody can answer, postpone the savings claim. For personal use, apply the same rule to time: a fast draft that takes an hour to repair did not save an hour.
“Cheaper per million tokens, or cheaper per approved job?”
— Ankita
The Last Word
Priya enters the meeting without recommending the cheapest model. She proposes a smaller experiment first: itemize one support workflow, restrict each request to the relevant tools, and count retries and review time alongside tokens.
That does not guarantee the rebuild will win. It makes the decision measurable. If the scoped workflow delivers equally acceptable answers for less total money, keep the model and fix the design.
If model charges still dominate, switch models. If human repair dominates, question the task itself.
The price page remains open on Priya’s screen, but it has lost its authority. The number that matters is no longer the cost of generating words. It is the cost of finishing work.