A prompt can’t guarantee that the AI model will build your code, execute and deploy your code as you expected. The real question is how a developer turns a capable answer into a dependable working process.
Through 2026, Anthropic turned more of that surrounding machinery into visible Claude Code controls. The advance wasn’t smarter conversation—it was giving ordinary developers practical ways to control what happens after the chat ends.
The Real-World Problem
You’ve seen the smaller version of this. An AI coding tool delivers an impressive answer, but you have no idea what it inspected, whether it tested the change, or what happens when a command fails halfway through.
A prompt can ask for carefulness. Carefulness isn’t a control. The model can misunderstand a requirement, edit unrelated files, build an elaborate solution for a simple problem, or declare victory after a shallow check.
Imagine that same behavior at a school support desk. An assistant drafts a convincing response about a student’s account, but it consulted an outdated record and never verified the change took effect. Fluent language hides a broken process.
The danger grows when the tool can act. Reading a document is relatively contained. Running shell commands, changing a database, calling an internal service, or handling credentials creates consequences far outside the chat window.
Recent user reports about Claude Code mention ignored instructions, unauthorized actions, and repeated mistakes. Those reports don’t establish a general failure rate, but they show why instructions can’t be the only defense. A service or model change can weaken behavior that once seemed dependable.
The developer needs more than a clever request. The process has to supply the right project information, restrict available actions, test the result, save progress, record failures, and ask for human approval when stakes rise. Without those pieces, automation just makes mistakes happen faster.
What’s Actually Going On
Harness engineering builds the control system around an AI model. Think of the model as a talented cook: a prompt is the order, and the harness is the kitchen, the recipe book, the ingredient supply, the timer, the hygiene rules, and the final inspection.
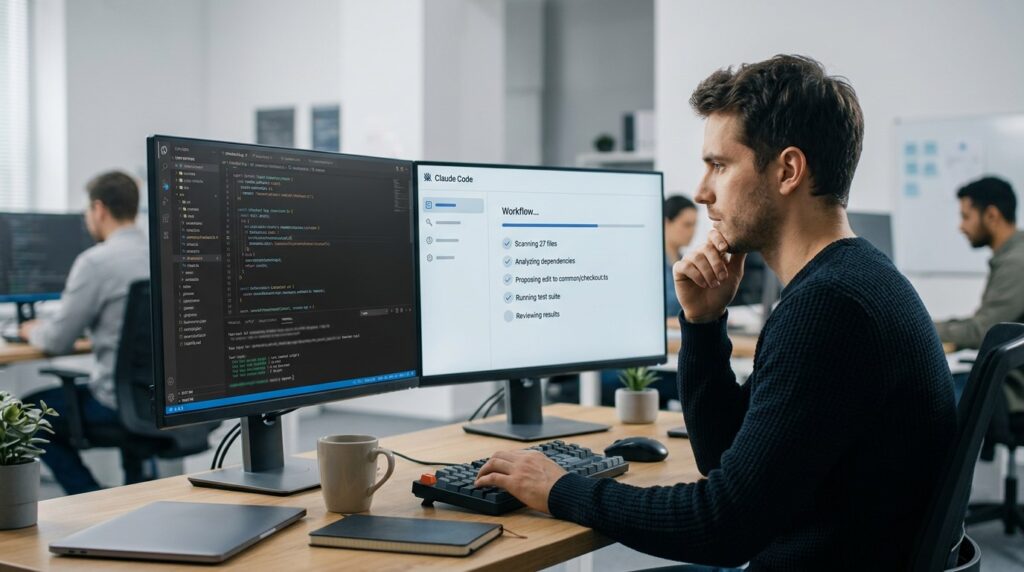
For Claude Code, that surrounding system starts with ordinary project files. A `CLAUDE.md` file holds persistent instructions about architecture and coding rules. Hooks are scripts triggered by events—like automatically running tests after an edit.
Skills load instructions for a particular job, while plugins package a tested setup for reuse.
Connections called MCP servers let Claude reach approved data or services. Picture one as a controlled doorway: the harness decides which doorway exists, what credentials open it, and which actions are allowed after entry. The model doesn’t get unlimited access automatically.
On March 24, Anthropic described a larger harness that separated planning, implementation, and evaluation. Work moved through structured files, and an evaluator interacted with the running application instead of trusting the model’s written claim that everything worked.
That evaluator found concrete faults. It caught an interface tool that failed to fill a selected area and a code condition that broke deletion. It also spotted an application route that handled a valid request as an invalid identifier.
These were working-software problems, not awkwardly worded answers.
On April 8, Anthropic detailed Managed Agents as separate sessions, harnesses, and sandboxes. A session preserves what happened, the harness sends requests and routes tool use, and the sandbox is the controlled place where code executes and files change.
Keeping those parts separate creates replaceable pieces. A team can change the model without rebuilding the execution area, or replace the execution area without losing the record of what happened. Failures become easier to inspect, and changes become easier to reverse.
On May 14, Anthropic documented how Claude Code could connect these ideas inside large codebases. It could read live files, follow references, use external systems, separate exploration from editing, and apply automatic checks.
This is different from prompt engineering. Prompt engineering improves what you say to the model. Harness engineering controls what information it receives, which tools it may use, where actions run, how results are checked, when failures trigger retries, and when a person must intervene.
Better instructions help—reliable machinery makes those instructions enforceable.
A dependable coding agent is a chain of separate controls, not simply a model following a better prompt.
Why It Matters
Useful AI software has to do more than produce a plausible answer. A support assistant must retrieve the correct account record. A coding agent must test its changes.
A shop’s automation must stop rather than repeatedly charging a customer when a service fails.
Harnesses make those behaviors repeatable. They can load current data, reject malformed results, limit permissions, retry temporary failures, preserve logs, and require approval before code is merged or infrastructure changes. A prompt can request these behaviors, but it can’t reliably enforce them outside the conversation.
They also make failure visible. If a command times out, a credential expires, or a test rejects an edit, the harness can record the event and stop safely. Without that record, the developer sees only Claude’s final explanation and may miss the failed action underneath.
Cost is the trade-off. In Anthropic’s own experiment, a short solo model run cost $9 and delivered a limited result. That figure works as a baseline, not a universal price.
The full harness cost $200 and produced a substantially more complete application. Anthropic supplied this comparison, so treat it as a company experiment, not an independent benchmark.
A later harness run cost $124.70 and still left missing features and defects. More orchestration can improve coverage, but it doesn’t guarantee quality.
Extra evaluators, retries, and context checks consume model usage and time. The right harness isn’t the largest one. It’s the smallest system that catches the failures that matter for the task.
Claude Code makes harness engineering approachable. A normal laptop is enough because model computation happens remotely. Cloud usage, secure permissions, strong tests, and human judgment stay necessary.
It removes the need to own a powerful graphics processor—it doesn’t remove the need to understand software.
Like fall protection, an AI harness does not do the work—it sets boundaries and provides a path to recovery.
See It In Action
Bad prompt: “Fix the checkout bug and clean up anything else you notice. Make sure everything works.”
What you get: Done. I refactored checkout, updated nearby utilities, and improved the database handler. Everything should work now. No test evidence, file list, or recovery point is provided. The confident answer gives the developer no practical way to distinguish a real fix from a larger hidden failure.
Better prompt: “Inspect the checkout failure. Change only necessary files, run the existing tests after edits, and stop for approval before database or infrastructure changes. Report failed tests and changed files. Save a recovery point first.”
What you get instead: The harness limits the task, records edits, and runs the project’s checks automatically. Claude reports the checkout fix, identifies the files changed, and surfaces a failing integration test. It does not touch the database because that action requires approval. A saved recovery point allows the edits to be reversed. The developer now reviews evidence, not confidence.
How To Use This Knowledge
-
Define success before Claude edits anything. Name the expected behavior, the affected area, and the checks that must pass.
-
Store stable project rules in a version-controlled instruction file instead of repeating them in every conversation. Keep task-specific details in the task.
-
Automate verification with hooks that run tests, formatting, and other required checks after changes, even when Claude says the work is complete.
-
Limit access so the agent receives only the files, tools, credentials, and network connections needed for the task.
-
Require approval before merging code, changing infrastructure, accessing sensitive information, or taking actions that are difficult to reverse. Preserve logs and a recovery point so a reviewer can inspect and undo the work.
Common Mistakes
-
Treating a stronger prompt as a substitute for permissions, tests, logs, and recovery procedures. Instructions describe desired behavior—controls enforce boundaries.
-
Letting Claude review its own work without independent checks. Anthropic found evaluators could become overly optimistic too. For important work, test observable behavior rather than accepting a written summary.
-
Loading every document into the conversation, which buries relevant information and weakens coherence during long tasks. Supply the smallest useful set and refresh it when the task changes.
-
Allowing broad tool access because setup is easier, even when the job needs only a narrow set of actions. A coding fix rarely needs unrestricted database or cloud permissions.
-
Keeping old instructions forever. Model changes can make elaborate scaffolding unnecessary or actively counterproductive. Review the setup after major model changes and remove rules that no longer earn their complexity.
Expert Insight
Anthropic’s most useful finding is that evaluation must itself be engineered. Its early evaluator sometimes performed superficial checks, accepted real defects, and missed deeper bugs. The company responded by making success criteria explicit and having the evaluator interact with running software—interfaces, application endpoints, and stored data.
That lesson extends beyond coding. A harness can make an AI system consistently wrong when its checks reward the wrong result. Passing a test matters only if the test represents what users actually need.
An automated shop assistant, for example, might pass a test confirming that it produced a refund message. The meaningful check is whether the payment system actually issued the correct refund once, updated the order, and created a record a staff member can inspect.
Evaluation also needs independence. A model that wrote the change has reasons to interpret unclear evidence generously, while a separate test can compare the result with an explicit requirement.
Let the model propose work, but let observable evidence decide whether the work passes.
In The Wild
AWS shows how harness engineering changes when it enters an organization. Claude Platform on AWS lets a company reach Anthropic’s native platform through its existing AWS account, identity controls, activity logs, and consolidated billing. Claude Code can then use AWS credentials while permissions govern who may invoke it.
This removes an administrative barrier, not the engineering burden. The company still needs to manage secrets, approve repositories and connected tools, decide where code may run, and establish review rules. Familiar billing doesn’t make an unsafe tool connection safe.
AWS also states that the service is operated by Anthropic and processes customer data outside the AWS security boundary. Organizations with strict location or processing requirements must distinguish it from Claude offered through Amazon Bedrock. The similar route through an AWS account doesn’t mean the two arrangements have identical boundaries.
AWS and Anthropic have also shown where richer harnesses may lead. AWS described a security workflow that could connect Claude Code to repository data, cloud configuration, a vulnerability scanner, and a sandbox before proposing a repair. As of the latest October update, that integration was still described as coming soon, so its current availability remained unconfirmed.
The example clarifies the concept. A prompt can ask whether code looks unsafe. A harness can combine the code with access policies and network exposure, validate a finding away from production, and place the proposed repair before a developer.
Back at the checkout project, the developer no longer asks Claude merely to be careful. Project rules supply context, permissions narrow its reach, automated tests expose the remaining failure, and approval protects sensitive systems. The model still writes useful code.
The harness decides whether that code is ready to matter.